Use clear, separate portraits
Choose one authorized adult per image with a visible face and a relaxed expression. Two clean portraits make left/right assignments easier to follow than a crowded group photo.
AI TRENDS / STORY & EMOTION
Create an AI Hotel Lobby duet in EveryGen AI. Edit the prompt, choose two photos and generate.
Generated videos are stored for 24 hours, then deleted. Download files you want to keep.
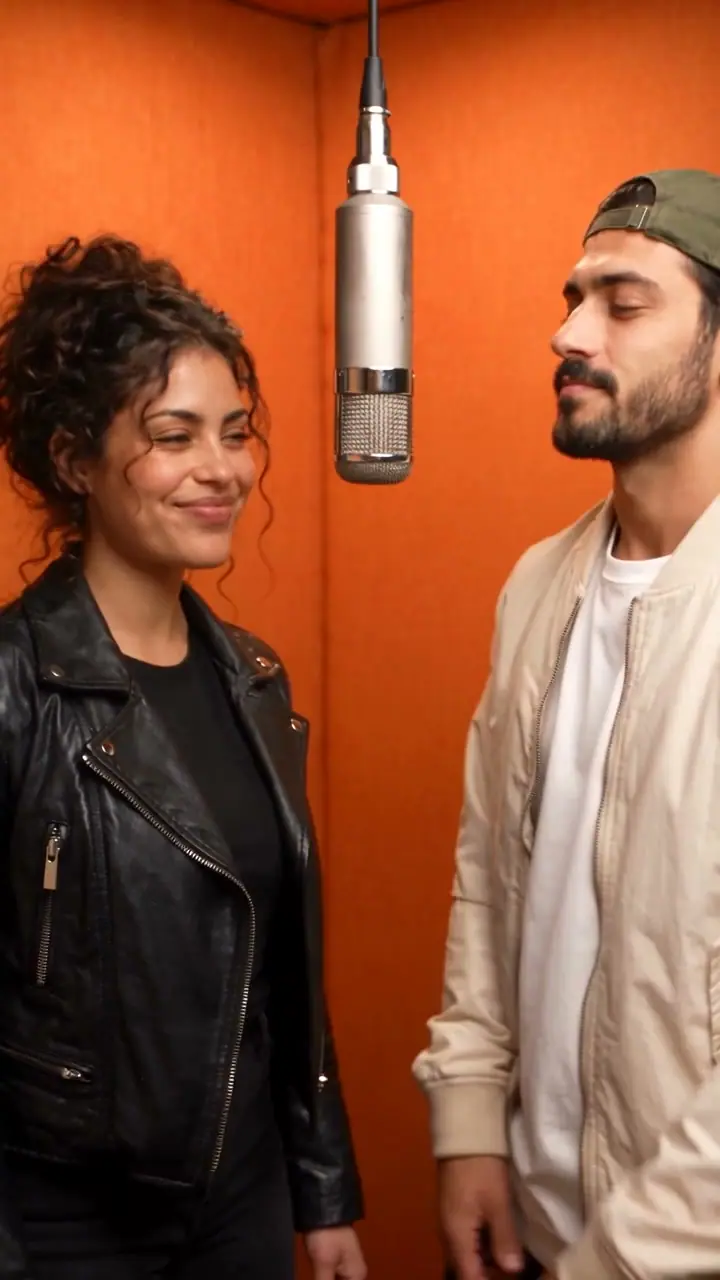
AI Hotel Lobby · 10s · Original sound. Your generated video appears here.Recorded source demo · Seedance 2.5 workspace
No generated videos yet.
Your inputs are saved while you work.This orange-booth demo was generated with Seedance 2.5 from two fictional adult portraits at 720 × 1280, with 10 seconds of original native music and vocals. The recorded prompt and left/right references are included below.
The original two fictional adult reference portraits are included. Reference image 1 is the woman on the left; reference image 2 is the man on the right.
Create a photorealistic fictional cinematic website promotional video, exactly 10 seconds. Exactly two clearly adult performers. Preserve reference faces and outfits. Natural anatomy, stable faces, expressive realistic movements, detailed setting. Generate a complete audible native soundtrack synchronized to the visible actions, from the first second to the ending. No subtitles, written words, logos, watermarks, extra people or voice impersonation. Original music and original lyrics only. Finish the action and music with a deliberate ending at 10 seconds. Reference image 1 is the curly-haired woman on the LEFT; reference image 2 is the man in a green cap and cream jacket on the RIGHT. A vivid warm orange acoustic recording booth, one silver microphone hanging between the two performers, premium tungsten editorial lighting. Keep both performers and the hanging microphone visible in a medium two-shot. 0-2s: the woman smiles and nods to the opening beat, the man responds with a shoulder groove. 2-6s: they trade playful short sung phrases with synchronized mouth movements and rhythmic hand gestures. 6-9s: both bounce in time and sing together. 9-10s: they share a confident final pose, music resolves. SOUND: a lively original 96 BPM hip-hop/funk groove, warm bass, crisp claps and hi-hats. Woman sings 'Two voices, one room'; man replies 'Bring that rhythm through'; together 'Orange light, we move'. Audible vocals must alternate with the corresponding performer; do not just pose silently. The orange booth and shared microphone are essential throughout.
The generator above starts with Seedance 2.5 at 10s / 9:16 / 720p with audio. Review the quote before generating. Original prompts do not guarantee identical results.
THE SCENE / YOUR CREATIVE DIRECTION
The AI Hotel Lobby format pairs two recognizable people in a warm recording-booth scene. Its visual anchors are simple: orange acoustic walls, a hanging microphone and a readable two-person shot. EveryGen AI’s example adds a short call-and-response performance with newly written vocal lines. The name describes this creative direction; the scene is a music booth rather than a hotel interior. Use it for a friendship duet, a playful couple performance or a character pairing with original sound.
The woman nods to the beat and the man answers with a shoulder movement.
The left and right performers alternate original sung lines.
Both performers bounce in time and sing together.
A shared final pose closes the scene as the music resolves.
These are the fictional adult portraits used in the recorded request. The workspace imports them after sign-in; replace them with your own authorized images if desired.
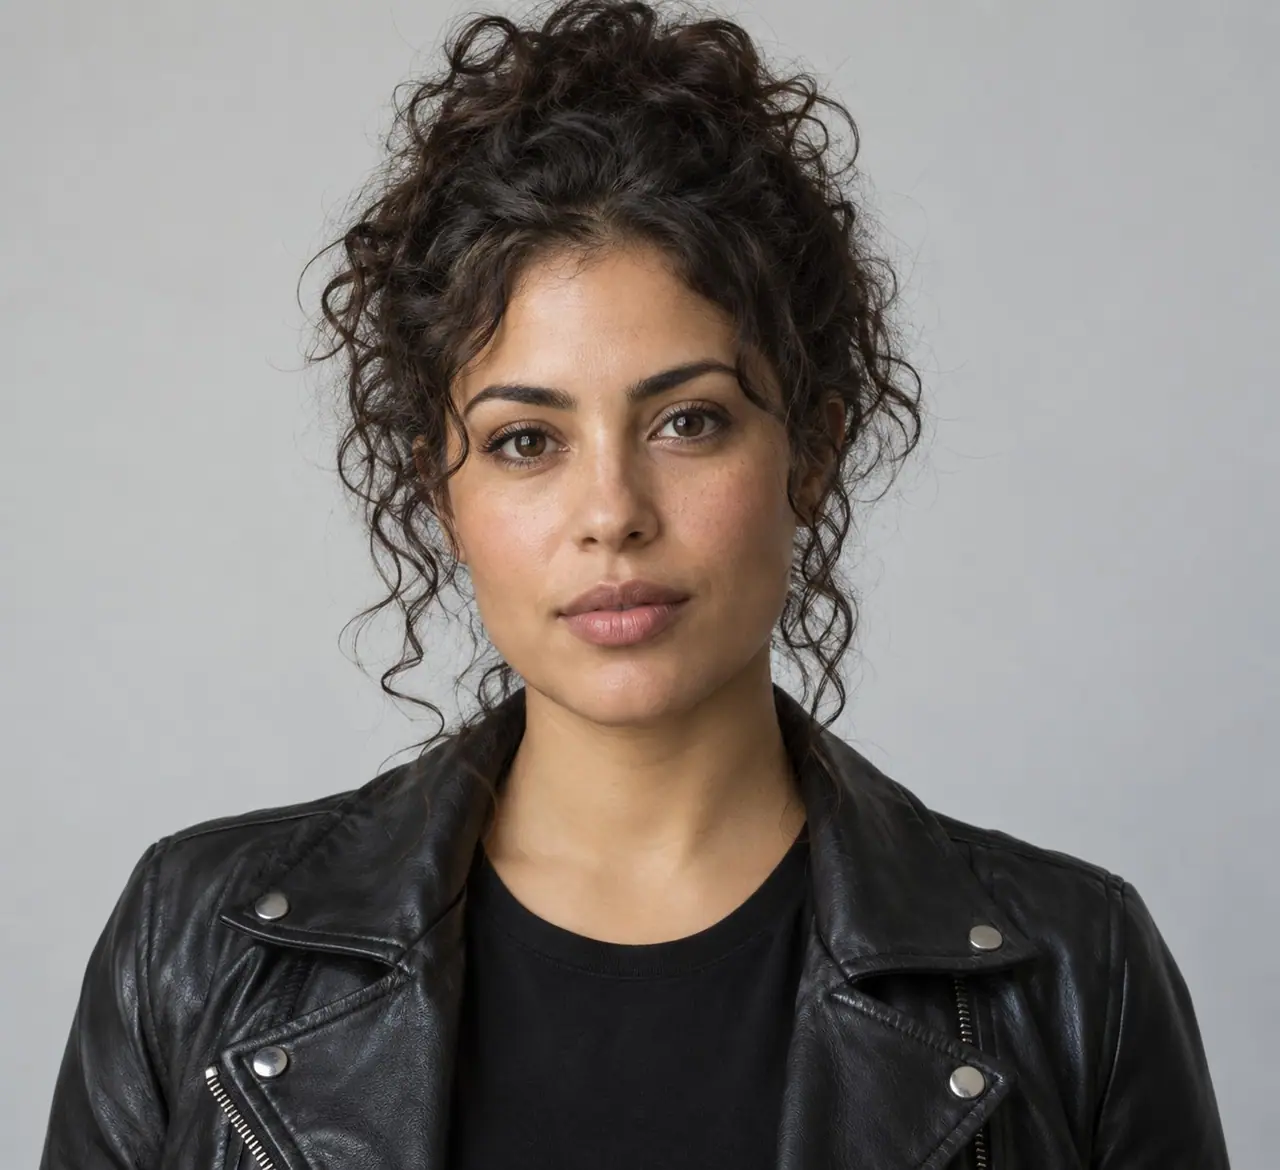
The first image defines the woman in the black jacket on the left. The original prompt gives her the opening smile and the first sung phrase.
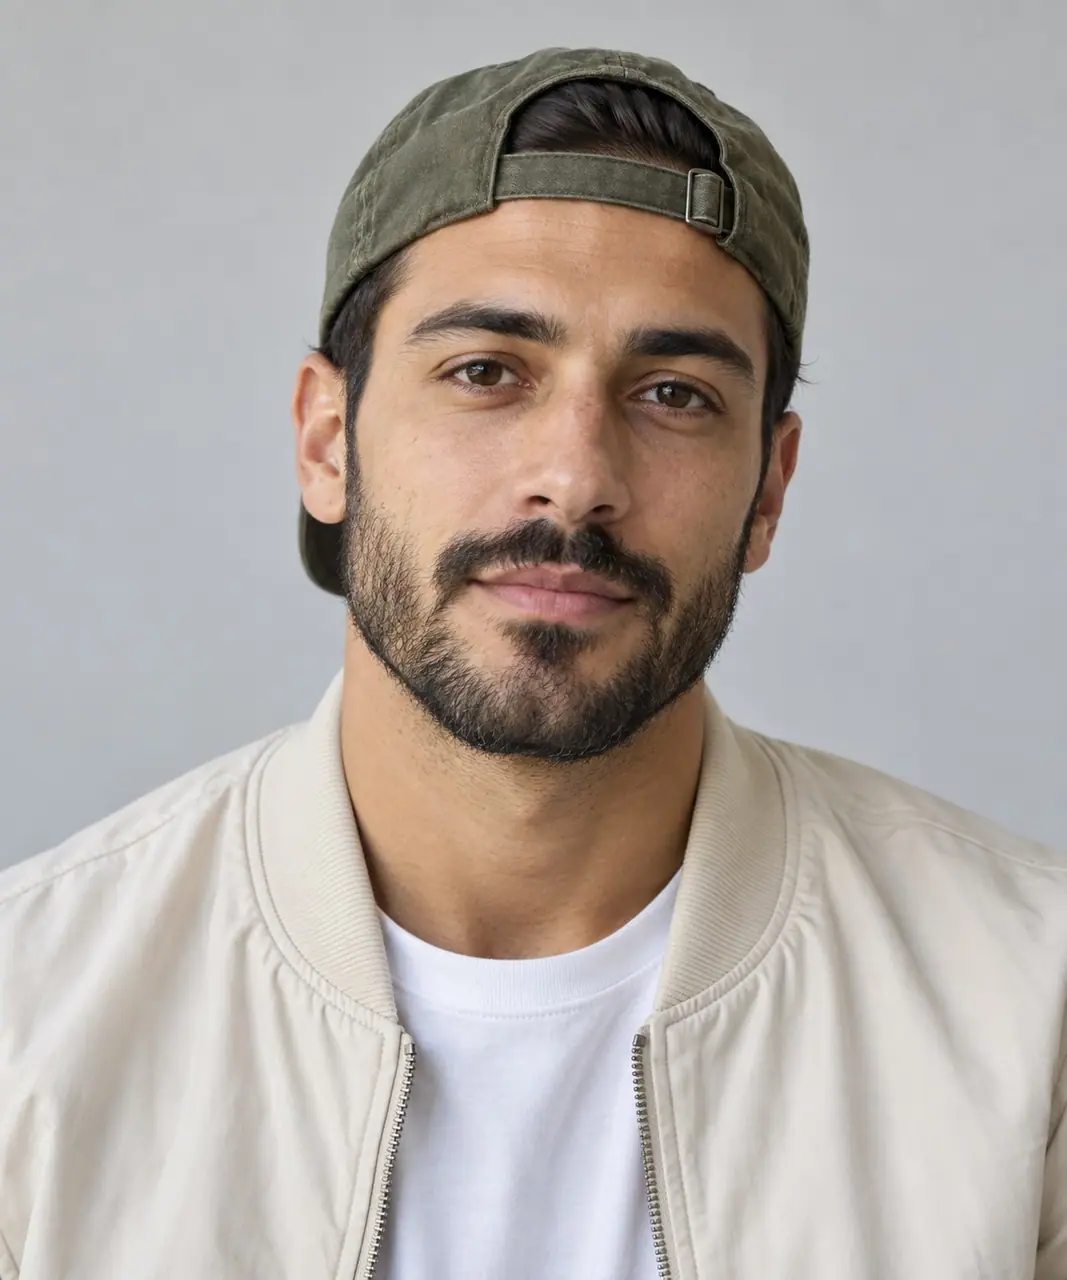
The second image defines the man in the green cap and cream jacket on the right. He answers the opening phrase before both performers sing together.
Prepare the identities and framing before opening a new take in EveryGen AI.
Choose one authorized adult per image with a visible face and a relaxed expression. Two clean portraits make left/right assignments easier to follow than a crowded group photo.
The first image belongs to the left performer and the second to the right. Swap both the files and their written roles if you want to reverse the duet; changing only one can confuse the scene.
Keep the hanging microphone between the performers and both faces visible in a medium two-shot. Extra close-ups and rapid camera cuts compete with the duet’s alternating vocal action.
If you rewrite the original lines, use brief phrases that can fit into ten seconds. Ask for original lyrics and music, then listen to the result and inspect which performer delivers each line.
Understand what the source brief controls before you edit it in EveryGen AI.
EveryGen AI includes the original portraits behind the demo. Import them after sign-in or replace them before generating; the prompt ties each image to its performer.
The source brief specifies warm editorial lighting, orange acoustic walls, one hanging silver microphone and a medium two-shot. Edit the mood while keeping the composition readable.
The ten-second request alternates newly written vocal phrases, then brings the performers together. Audio is enabled in the matching setup; the output is a newly generated performance.
Start with the recorded prompt, choose your inputs and inspect the new take.
The generator is already open above with the recorded original prompt and compatible settings. Edit the scene directly; you do not need to open a separate example or template.
Sign in to load the two fictional adult samples. You can replace them with your own authorized portraits; keep the file order, clothing and performer descriptions consistent.
Change the original phrases, gestures or lighting in the workspace. Review the current credit quote and account permissions before submitting the new take.
Follow the task in Creations and inspect each performer’s identity, mouth movement and sound. Download the finished file before the displayed 24-hour expiry.
Use the finished video to choose one useful change for your next EveryGen AI take.
Keep the left/right assignments and the timed call-and-response instructions. Ask for both performers in frame, then check that neither portrait is missing.
Simplify the lyrics and reduce overlapping actions. Review the full generated take; native singing and lip movement are model-generated and may need another version.
Retain orange acoustic walls and the shared hanging microphone as essential scene details. Remove conflicting location instructions before making the next take.
Prompts, reference inputs, source models and your new video.
It is a two-person performance style recognizable by its warm orange booth and shared microphone. EveryGen AI provides an independent two-photo workflow with a recorded example and original sound.
This page makes the orange-booth duet video format. It does not design hotel interiors or floor plans. You can describe other video settings in the general EveryGen AI workspace.
Yes. The original completed orange-booth request was matched to the saved video, and the full prompt is provided without rewriting. The two source portraits are included.
Yes. Upload two authorized adult portraits in the prepared multi-reference workspace, assign one to each side and adjust the written descriptions to match.
The demo uses original generated music and newly written English lines. It does not include a commercial song, an artist recording or a voice clone.
Faces, gestures, vocals and timing can vary between generations. The original references and prompt give you a concrete starting point; inspect the full new take before sharing it.
EveryGen AI offers credit packs, video passes and subscriptions. This setup requires enough credits or an eligible purchase covering its model and settings. Review the quote and plan permissions in the workspace.
That guide uses the same recorded duet to explain reference roles. This AI Hotel Lobby page focuses on making the orange-booth performance itself. Both pages point to the same original prompt and source portraits.