One continuous performance
The source brief keeps the lead and speaker-holder in a readable medium-wide phone shot. A single scene gives the model room to maintain faces, hands and the speaker.
AI TRENDS / STREET & PERFORMANCE
Bring the street freestyle format into EveryGen AI. Watch the original fictional performance, copy its real generation prompt and shape your own scene.
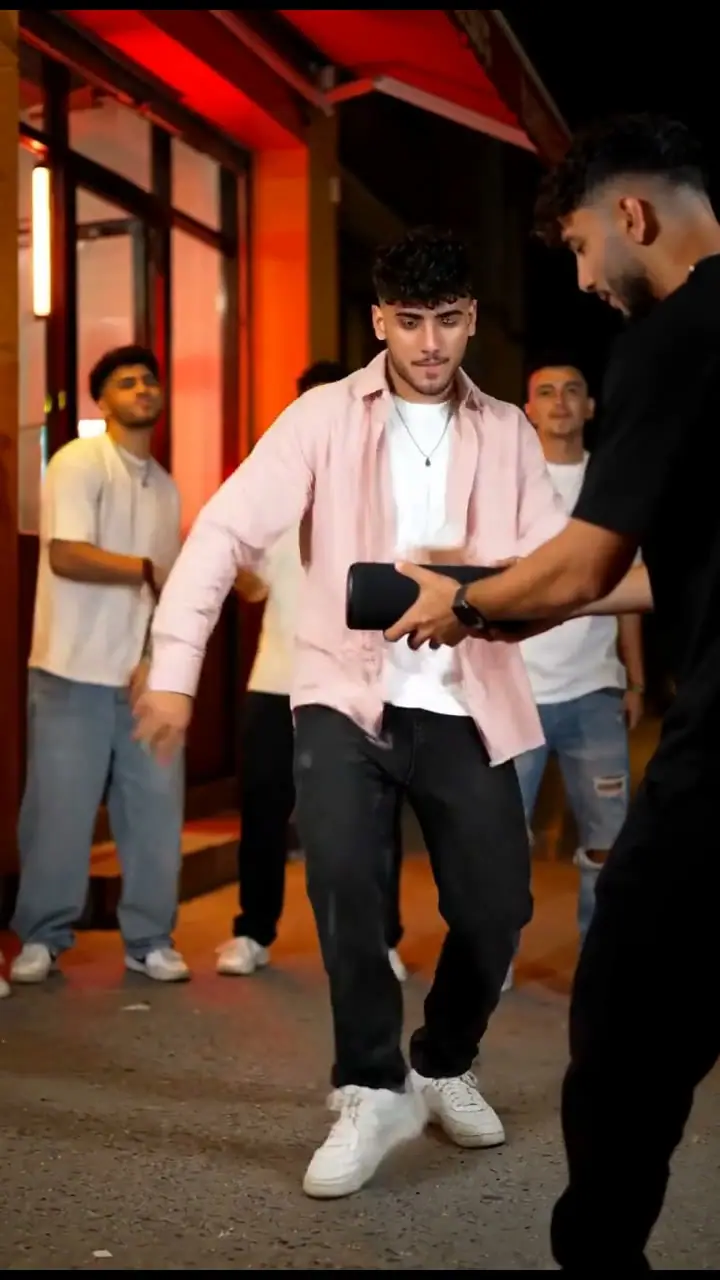
The source demo was generated with MiniMax H3 at native 768p, then exported to 720 × 1280. The exact text-only prompt is preserved below. Your new take uses the supported Seedance 2.5 workspace; it is not an artist impersonation or an existing recording.
THE RECORDED SOURCE
Text prompt only; the demonstration uses fictional adults.
Create a photorealistic original fictional 10-second vertical 9:16 street freestyle performance. All subjects are clearly adults with invented faces, no real artist likeness or voice imitation. In front of a small restaurant at night, warm red and amber light spills onto a pavement. The lead is a fictional 28-year-old man with short dark curly hair, an open pale pink overshirt over a white T-shirt and charcoal trousers. A fictional adult friend at the side holds one portable black Bluetooth speaker with a stable two-handed grip. Three original adult background friends cheer softly out of focus. 0-2 seconds: the lead smiles toward the handheld phone camera as the original dembow beat begins. 2-7 seconds: he does compact rhythmic footwork, loose shoulder bounces and expressive open-hand gestures, staying behind the friend holding the speaker; he delivers the newly written Spanish line 'La noche se enciende, mi ritmo sorprende' in his own fictional voice with natural matching mouth movement. 7-10 seconds: he finishes one small dance step, gives a playful final hand gesture and holds a confident ending as the music resolves. A single continuous handheld medium-wide phone-camera shot, both featured adults visible, natural proportions and realistic hands. AUDIO: create an entirely original upbeat 100 BPM dembow groove with syncopated percussion, warm bass, the original lead vocal phrase and small crowd cheers, synchronized to the visible movement. Do not reproduce any real song, existing video, real performer or copyrighted lyrics. No text, captions, brand names, logos, extra fingers, floating speaker or face morphing. The video is an original AI demonstration inspired by a street freestyle format, not real footage.
Preparing a new take opens Seedance 2.5 at 10s / 9:16 / 720p with audio. Review the quote before generating. Original prompts do not guarantee identical results.
Understand what the source brief controls before you edit it in EveryGen AI.
The source brief keeps the lead and speaker-holder in a readable medium-wide phone shot. A single scene gives the model room to maintain faces, hands and the speaker.
The recorded prompt specifies an opening smile, compact footwork and a deliberate ending. Keep these beats or edit one movement at a time.
The source request contains an original dembow groove and newly written Spanish vocal phrase. Audio is enabled in the prepared setup; review the new take for timing and pronunciation.
Start with the recorded prompt, choose your inputs and inspect the new take.
Copy the complete prompt or open it in the workspace. The demo was text-to-video with fictional adults; it does not require an uploaded portrait.
Change the lead, clothes or setting. To use your own authorized portrait, switch to a supported image or multi-reference input and attach that image before submitting.
The prepared setup is 10 seconds, 9:16, 720p with audio. Review the model-specific quote, then inspect motion and sound in Creations before downloading.
Prompts, reference inputs, source models and your new video.
It is a street-freestyle scene direction with a lead performer, a portable speaker and a supporting crowd. EveryGen AI offers an independent prompt workflow, not an official artist product.
Yes. It was recovered from the completed generation request and matched to the original saved video. The complete prompt is displayed and copied without rewriting.
The source model and the new generation model differ. The original prompt is reusable, but faces, timing, music and choreography may change.
Yes. Change to a supported image or multi-reference mode and use an authorized adult portrait. Edit the text-only description so the image clearly defines the lead.
The recorded prompt asks for original music and a fictional voice. No artist recording, artist likeness or existing lyrics are supplied.